Links
- Documentation: https://mbustama.github.io/FeldmanCousins/
- Tutorial notebooks: https://mbustama.github.io/FeldmanCousins/tutorials.html
- Source code: https://github.com/mbustama/FeldmanCousins
Setting a confidence interval sounds like a solved problem, until you actually have to do it. Deciding whether to quote a two-sided interval or a one-sided upper limit after looking at the data — the classic “flip-flopping” — breaks coverage, and near a physical boundary (a mass, a cross section, a flavor fraction) the usual construction can return an empty or unphysical interval. Feldman and Cousins’ 1998 unified approach fixed this by using the likelihood-ratio ordering principle to let the data decide the interval’s shape automatically, with guaranteed coverage throughout. It has become the standard approach for small-signal counting experiments across particle and astroparticle physics — but implementing it correctly, especially in more than one dimension and with realistic, finite-statistics systematics, is a substantial piece of software to get right.
That’s what I built PyFC to handle — it supports binned and unbinned likelihoods natively, in the same framework, rather than treating one as a special case of the other. Given a likelihood, it runs the Monte Carlo pseudo-experiments needed to empirically calibrate the profile-likelihood-ratio distribution, and returns exact-coverage Feldman-Cousins intervals and contours — in one or several dimensions, on a laptop or on a cluster. I kept needing exactly this — correct-coverage contours for neutrino mixing-parameter extractions and HNL coupling limits in my own papers — and rewriting the toy-generation machinery from scratch for each project wasn’t sustainable.
If your reference point is ROOT/RooStats’ FeldmanCousins calculator: PyFC does the same statistical job with no ROOT dependency — plain NumPy/SciPy arrays and a pip install, so it drops straight into a normal Python analysis.
Main features
PyFC is built for speed, flexibility, and accuracy — none traded off for the others.
Speed
- Parallel processing by default. Binned fits use Numba/NumPy C-extensions with GIL-bypassing thread pooling; unbinned fits parallelize across CPU cores via Python’s multiprocessing (
ProcessPoolExecutor). Toy generation — normally the bottleneck in any Feldman-Cousins analysis — scales with however many cores you give it. - No wasted compute. Adaptive early-stopping (
adaptive_toys) and batched dispatch (toy_batch_size) stop generating toys once the result is statistically clear, instead of running a fixed, oversized number every time. - Resumable. Checkpointing saves state after each parameter/pair scan, so a run killed by a cluster walltime limit picks up where it left off instead of restarting from zero.
Flexibility
- Native binned and unbinned support, in one framework. Poisson binned data — including arbitrary N-dimensional, even non-contiguous, histograms — and Extended Unbinned Maximum Likelihood models are both first-class, not one bolted onto the other.
- A choice of optimizer. Gradient-based SciPy (L-BFGS-B), nested sampling via UltraNest, brute-force grid scans, or a Hybrid strategy that uses UltraNest’s robustness for the one global fit and SciPy’s speed for the many conditional fits that follow.
- Physical constraints between parameters, not just per-parameter boxes.
bounds_funcandconstraintsexpress joint or simplex conditions (e.g. a + b ≤ 1) that an independent [lo, hi] range per parameter can’t capture.
Accuracy
- Coverage that’s actually exact. The test-statistic distribution is derived empirically from generated toys rather than assumed from Wilks’ theorem, and disconnected accepted regions are reported as separate intervals instead of being silently merged into one.
- Finite-Monte-Carlo corrections for limited simulation statistics, so a small MC background template doesn’t bias the result.
Also: optional 2D grid sparsification for faster contours, and an interactive CLI for generating run configurations.
Open source (GPLv3), Python 3.8+.
What you need to provide
You bring the physics, PyFC handles the statistics:
- A physics mapper — for binned data, a
compute_rates_functhat maps your free parameters to expected bin counts and variances; for unbinned data, that pluspdf_components(one function per signal/background component) and agenerate_toy_funcfor parametric bootstrapping. - Your data — a histogram (any shape, any dimension) or an array of events.
grids— the scan grid for each free parameter, plusbounds_func/constraintsfor any joint constraints between them.- A config — confidence level, toy settings, checkpointing, and the optimizer strategy (
grid,scipy,ultranest, orhybrid), built interactively with the CLI or as a JSON file.
Call compute_fc_intervals and PyFC takes care of the rest: toy generation, parallelization, checkpointing, and exact-coverage intervals out the other end — no hand-rolled Monte Carlo loop required.
A minimal example
For a binned Poisson analysis with a signal and a background component:
import numpy as npfrom numba import njitfrom pyfc import compute_fc_intervals# A fixed expected-shape array, captured via closure (not itself a fit parameter)expected_shape = np.array([0.1, 0.5, 2.0, 5.0])njit(fastmath=True, nogil=True)def compute_rates(params): """Map parameters -> expected bin counts (mu) and variances (sigma2).""" mu = params[0] * params[1] * expected_shape + params[2] # signal (rate x efficiency) + background sigma2 = mu # Poisson variance return mu, sigma2observed_counts = np.array([20, 7, 2, 0]) # data — any shape, not just 1Dgrids = [ np.linspace(1e-9, 1e-7, 20), # param_1 np.linspace(2.0, 3.0, 15), # param_2 np.linspace(0.8, 1.2, 10), # param_3]# results: exact-coverage FC intervals/contours for param_1-3, plus the# underlying profile-likelihood scan and toy statistics behind themresults = compute_fc_intervals( data=observed_counts, grids=grids, compute_rates_func=compute_rates, **config, # confidence level, toy settings, strategy — see Configuration)
(See the Quick Start Guide for the full binned and unbinned walkthroughs, with real output.)
Install with:
pip install PyFeldmanCousins
Some physics it’s meant for
Feldman-Cousins intervals matter most exactly where physics tends to live: near a boundary, with a marginal signal, where Gaussian/Wilks assumptions don’t hold. A few non-trivial cases PyFC is a natural fit for:
- Astrophysical neutrino flavor composition. The flavor fractions (f_e, f_μ, f_τ) of the diffuse high-energy neutrino flux live on a simplex, f_e + f_μ + f_τ = 1 — precisely the joint-constraint case that
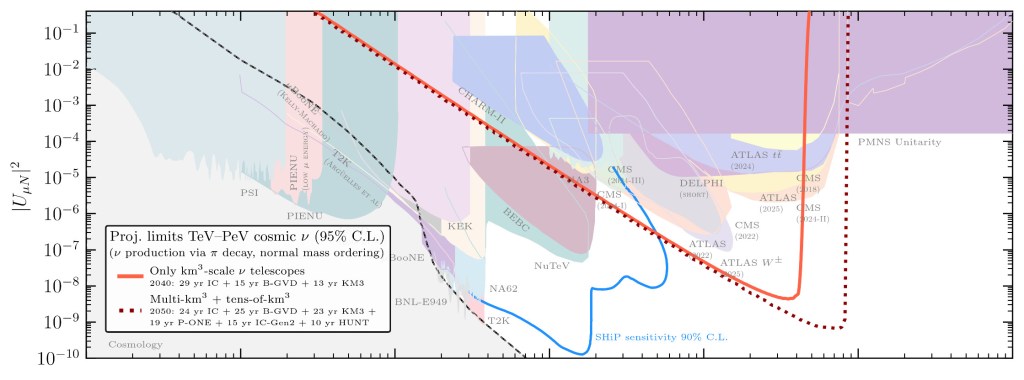
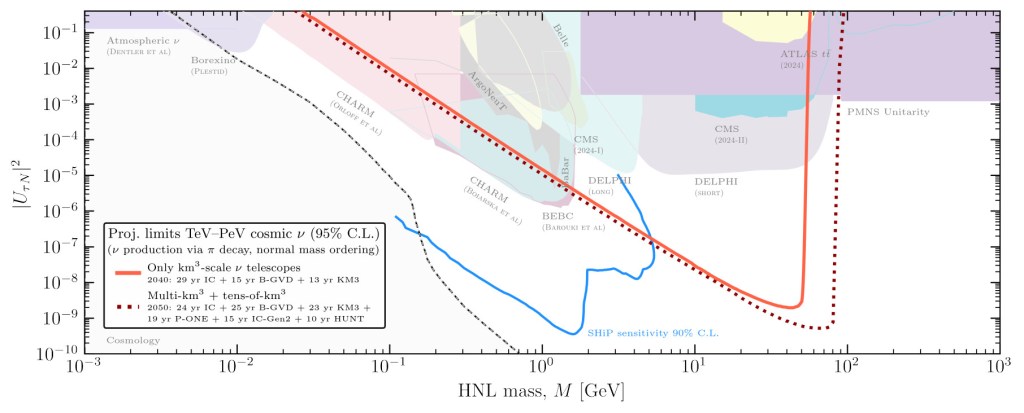
bounds_func/constraintswere built for. Feldman-Cousins contours on the flavor triangle are the standard way to compare an IceCube-like measurement against competing production scenarios (pion decay, muon-damped decay, neutron decay) and BSM flavor physics. Worked through hands-on in tutorial notebook 06. - Heavy Neutral Lepton searches at beam-dump experiments. A null result from a fixed-target experiment like SHiP constrains the active-sterile mixing |U|² as a function of HNL mass — an upper limit sitting right against the |U|² ≥ 0 boundary, often with disconnected sensitivity islands where the excluded region reappears at higher mass — see tutorial notebook 04 for how PyFC reports these correctly.
- Dark matter direct-detection cross-section limits. The textbook case: a handful of candidate events over an uncertain background, where the interval needs to turn two-sided smoothly if a real excess ever shows up, instead of flip-flopping into an artificially tight one. The quickstart tutorial notebook works through essentially this case end to end.
- Accelerator and reactor neutrino oscillations. Joint 2D regions on (Δm², sin²2θ) — this is literally the original 1998 Feldman-Cousins worked example, and still a good stress test for comparing the grid, SciPy, and Hybrid strategies — see tutorial notebook 05.
- Neutrinoless double-beta decay. Binned searches for a peak near the Q-value, where the finite-MC correction matters because the simulated background templates are themselves statistics-limited — see tutorial notebook 04 for the correction on vs. off.